
Recruiters: One-Page Performance Summary Templates and AI Prompts
Overall fit: Strong — the candidate cleared every core technical dimension with linked evidence and no integrity flags. That one-line verdict, backed by a single-sentence rationale tied to role-critical proof, is what a usable performance summary leads with every time. Everything else, from strength bullets to rubric scores, supports that opening call rather than burying it.
TL;DR:
- Candidates who clear all core technical checks typically demonstrate consistent, fully tested work with no integrity flags, supporting the strong fit verdict.
- Evidence for strengths should be specific, timestamped, or quoted, while gaps or concerns are identified by exact moments or submissions revealing weaknesses.
- Assessment scores are relative ranges; a score near the cutoff warrants manual review of evidence rather than automatic rejection.
- A one-page summary, with the verdict first and bullets limited to three to five for strengths and concerns, promotes faster, clearer decision-making.
- Human review is essential for borderline scores, with explicit tagging of factual versus inferred traits and documentation of score overrides for audit purposes.
Table of Contents
- What Do Performance Summary Examples Look Like in Practice?
- How Do You Write a Performance Summary That Panels Actually Read?
- How Should You Present Rubric Scores and Score Ranges?
- When Should You Override an AI-Generated Score?
- How Talent Approved Builds This Into the Review Process
- A Practical Note From the Field
- Try the Template Workflow Without Building It Yourself
- Sources
- FAQ
What Do Performance Summary Examples Look Like in Practice?
A performance summary is not a transcript, and it is not a dashboard screenshot. It is a compressed, decision-ready document that puts the verdict first and backs it with just enough evidence to defend the call. Reports built this way put the fit call at the top and cap strengths and concerns to 3 to 5 bullets each, with one supporting quote or evidence line per bullet.
Here is what that looks like across three common outcomes recruiters need to communicate: hire, possible, and hold.
Hire or finalist template
- Verdict: Fit: Strong. One sentence tying the call to the most role-critical evidence (example: “Cleared all backend architecture checks with clean, tested code on the first attempt”).
- Strengths (3 bullets, one evidence line each): Specific skill, task, or answer that proves it. Timestamp or excerpt reference where relevant.
- Concerns (2 bullets, one evidence line each): Named gap, with the exact moment or submission that revealed it.
- Dimension snapshot: One sentence per rubric row (see the next section for format).
- Integrity note: Clean session, or flag with detail.
- Next steps: Schedule panel round, or move to offer stage.
Possible template
- Verdict: Fit: Possible, contingent on [specific gap].
- 3 to 4 bullets covering what worked, each with one evidence line.
- 2 bullets naming the gap and a proposed follow-up, such as a targeted re-test or a 20-minute technical follow-up call.
- Dimension snapshot with the borderline row flagged explicitly.
Hold or not recommended template
- Verdict: Fit: Not recommended for this role, stated plainly and without editorializing.
- 3 bullets on what the candidate did well, so the record stays fair.
- 2 to 3 bullets on the specific gaps that drove the decision, each with evidence.
- One line on whether the candidate fits a different open role.
Every version holds to the same constraints: one-line verdict, 3 to 5 bullets per category, one sentence per dimension. That discipline is what keeps a panel of five reviewers reading the same document the same way.
How Do You Write a Performance Summary That Panels Actually Read?
Most summaries fail for one reason: they were written to document effort, not to drive a decision. Fixing that starts before the candidate ever finishes the assessment.
- Fix the decision dimensions with the hiring manager first. Agree on 4 to 6 rubric rows (technical accuracy, communication, problem solving, whatever matters for the role) before results come in. Fixed dimensions make candidates comparable, and a rubric changed midstream ruins that.
- Collect evidence per dimension as you go. A quote, a timestamp, a code snippet, a submission excerpt. Vague impressions do not survive a panel challenge.
- Instruct the AI with an exact prompt pattern. Specify the output format, cap bullets at 5, require one evidence line per claim, and instruct it to mark any inferred trait (like “likely collaborative”) separately from stated facts (like “led a team of four”).
- Enforce length discipline. One page. Capped bullets. One sentence per dimension note. This is the single habit that separates a document a hiring manager reads in ninety seconds from one that gets skimmed and ignored.
- Add an integrity summary with a link to detail. A single line (“No flags, full session recorded”) satisfies most reviewers; link out to the full session log for the ones who want to check.
Pro Tip: Build your AI prompt once, save it as a template, and reuse it across every role. Consistency across summaries matters more than perfecting any single one.
How Should You Present Rubric Scores and Score Ranges?
Every dimension row needs four things: the label, the rating, one-line evidence, and a flag for whether that rating is stated or inferred. Skip the flag and you invite a panel to treat a guess as a fact.
A generic 4-point rubric row might read like this:
| Dimension | Rating | Evidence | Basis |
|---|---|---|---|
| Technical accuracy | Strong | Passed all 4 test cases on first submission | Stated |
| Communication | Average | Clear explanation of logic, some hesitation under time pressure | Stated |
| Problem solving | Strong | Chose the more efficient of two valid approaches unprompted | Stated |
| Culture fit signals | Average | Answers suggest collaborative style, not directly tested | Inferred |
Scores are ranges, not verdicts on their own. Assessment results are relative and carry measurement error, which means they should be read against role-specific norms rather than treated as hard cut-offs. A candidate scoring just below a threshold deserves a second look rather than an automatic rejection, especially on a dimension with a small sample of evidence behind it.
- Present the weighted total once, near the verdict, not scattered across the page.
- Show the per-dimension math only if a reviewer asks; the summary itself should stay on one page.
- Flag any dimension where the score sits within a few points of your cut-off as “near threshold” so reviewers know to read the evidence line instead of trusting the number alone.
When Should You Override an AI-Generated Score?
AI auto-scoring tools typically show expandable star breakdowns and written rationales that a reviewer can open before accepting a label. Treat that rationale as the first thing to check, not the score itself.
- Check the evidence link first. Open the linked transcript, code sample, or video clip behind the score. If the rationale does not match what you see, that is your override trigger.
- Check integrity flags. Any flag changes how much weight the score deserves, regardless of the number attached to it.
- Override at the rule level. Most platforms let you flip a specific rule or adjust a star rating, and the weighted total recalculates automatically once you do.
- Escalate borderline cases. If a candidate sits within roughly a point of your cutoff on a role-critical dimension, route it to a panel or request a short human re-test rather than trusting one automated score.
- Log the change. Record who overrode the score, why, and the new weighted total. That audit trail is what protects the decision later.
Statistic Callout: A near-threshold score is a review trigger, not a rejection. Treat any dimension score within a narrow band of your cutoff as a signal to check the evidence line yourself, since assessment results carry measurement error by design.
How Talent Approved Builds This Into the Review Process
Every template and checklist above maps directly onto features built into Talent Approved’s platform. Magic Create generates the role-specific rubric in minutes from a job description, so the dimensions are fixed before the first candidate finishes testing. The AI-generated summary that comes out the other side follows the same discipline: verdict up top, evidence-linked ratings, and a one-page layout instead of a raw data dump.
- Structured rubrics replace ad hoc scoring with consistent, comparable dimensions across every candidate. See the platform’s candidate evaluation criteria checklist for how those dimensions get defined.
- Anti-cheat monitoring, including screen and webcam checks, feeds the integrity note directly into the summary.
- Session replays and evidence links let a reviewer verify a rating in seconds, the same override workflow described above.
- Candidate rankings carry the weighted totals forward so a panel can compare finalists without rebuilding a scorecard by hand. Read how fast candidate evaluation works for recruiters for a closer look at the mechanics.
A Practical Note From the Field
Three mistakes sink most performance summaries: changing rubric dimensions between candidates, writing reports long enough to bury the verdict, and treating an AI score as final instead of a starting point for review.
Three fixes work fast. Cap every summary at one page. Put the verdict in the first line, always. And require a human check on any score sitting near your cutoff before it decides someone’s outcome. Try these templates on your next shortlist before your next full hiring round. You will notice the difference in how fast your panel actually agrees.
— Jimmie
Try the Template Workflow Without Building It Yourself
The platform turns everything in this guide into something you don’t have to build by hand. It can write a rubric from a job description, gather integrity notes automatically, and produce a verdict-first, evidence-linked AI-generated summary as described.
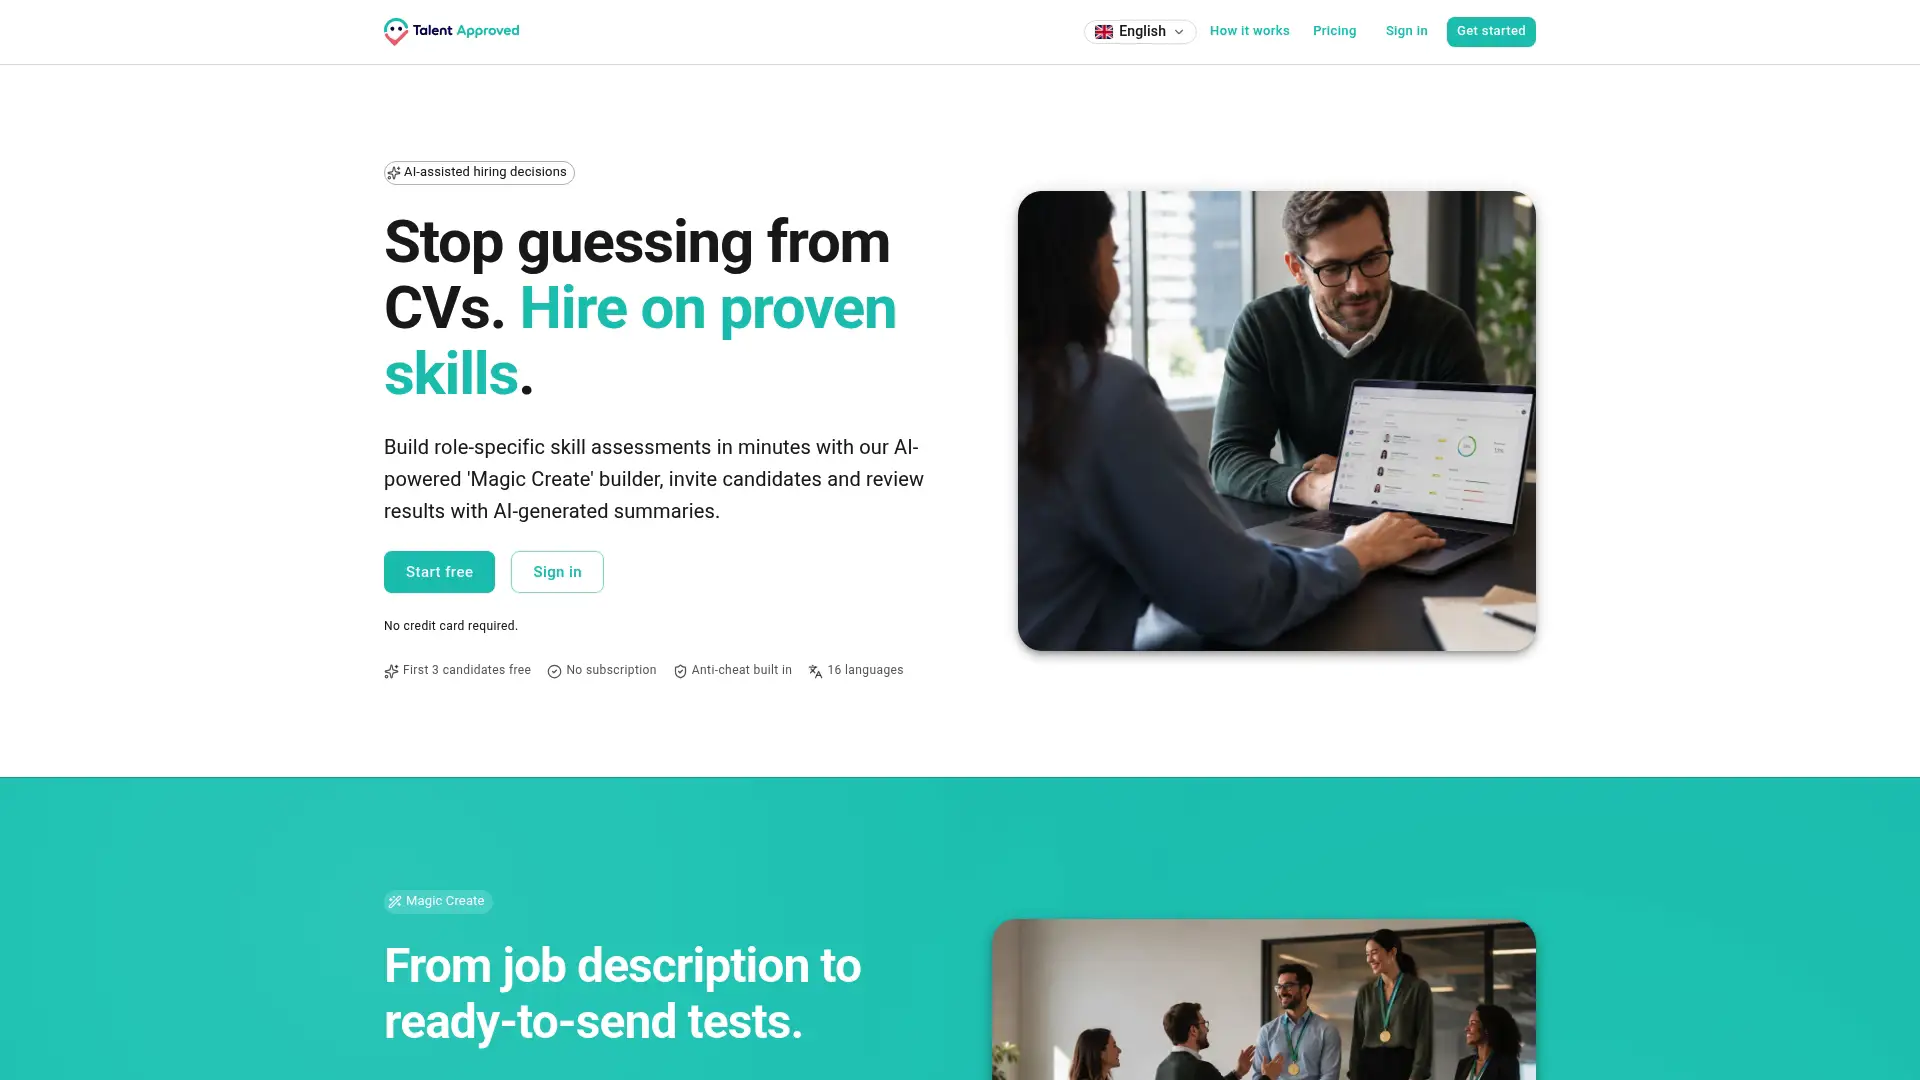
There is no subscription to commit to first. Talent Approved runs on a pay-as-you-go model: $5 per candidate who completes an assessment, detailed on the pricing page. Run one role through it, compare the summary you get against the templates above, and decide from there whether it fits your hiring workflow.
Sources
- Sharing Interview Results With Hiring Stakeholders: PDF Reports Done Right | ClarityHire
- Skill
- How Do You Review AI Auto-Scoring Results in Canditech? | Canditech Help Center
- A Step-by-Step Guide to Interpreting Skill Assessment Results | Riot IQ
FAQ
What Is the Ideal Length for a Candidate Performance Summary?
One page, with strengths and concerns capped at 3 to 5 bullets each and one sentence per rubric dimension. This length forces evidence-backed, decision-ready writing instead of a data dump a hiring manager has to dig through.
How Do You Separate Stated Facts From Inferred Traits in a Summary?
Tag every claim as either directly observed (a completed task, a quoted answer) or inferred (a personality trait guessed from behavior). Explicitly marking inferences protects candidates from being downgraded on traits nobody actually tested.
Can You Override an AI-Generated Score, and How?
Yes. Most platforms let a reviewer flip a rule-level rating or adjust a star score, and the weighted total recalculates automatically once the change is made. Log the reason for the override so the decision holds up under later review.
How Much Does Talent Approved Cost per Candidate?
Talent Approved charges $5 per candidate who completes an assessment, with no subscription required, as listed on its pricing page. You only pay for completed tests, not for building or sending the assessment itself.
Should a Borderline Score Automatically Disqualify a Candidate?
No. Scores near a cutoff should trigger a closer look at the evidence line rather than an automatic rejection, since assessment results are relative and carry measurement error. Treat the number as a signal to investigate, not a final ruling.